

HAMi Meetup Shanghai Deep Dive (1): Where Does HAMi Fit in the CNCF × PyTorch Cloud Native AI Foundation?
 Community & updates
The model runs, yet the business never ships; one team waits for GPUs while another's sit idle. In his opening keynote at HAMi Meetup Shanghai, CNCF China Director Keith Chan laid out a layered view of a cloud native AI R&D foundation — with HAMi in the scheduling and resource management layer, handling heterogeneous compute sharing. Understanding that position tells you what HAMi solves, and which components it needs alongside it.
On this page
The model runs, yet the business never ships. One team waits for GPUs while another team's devices sit underused. For enterprise AI platform teams, the hard part usually sits at the seams between models, toolchains, and infrastructure. As model counts grow, those gaps turn into cost, collaboration, and operational pressure.
This is the first deep-dive in our HAMi Meetup Shanghai series. Keith Chan, CNCF China Director and Linux Foundation APAC Vice President, opened the event with "CNCF x PyTorch: Building a Cloud Native AI R&D Foundation for Industry Adoption," offering a layered collaboration model. In it, HAMi occupies the scheduling and resource management layer, responsible for heterogeneous compute sharing and management. From an enterprise platform perspective, understanding that position is what lets you judge what adopting HAMi solves — and which other components you still need.
Key Takeaways
- HAMi sits in the scheduling and resource management layer, dividing labor with model frameworks and workflow components.
- HAMi-core's collaboration with KAI Scheduler shows how sharing controls can plug into different scheduling systems.
- Enterprises can start with one training job and one inference service to verify that resource request, execution, and observation actually connect.
Speaker: Keith Chan | CNCF China Director, Linux Foundation APAC Vice President
The Foundation Exists to Break a Chain of Cost, Efficiency, and Scale Problems
Keith framed the challenges of enterprise AI adoption as runaway cost, efficiency bottlenecks, and limited scale.
Cost pressure goes beyond GPU purchase price. Without unified scheduling, small jobs hold devices indefinitely and idle capacity never reaches other teams. Repeated environment setup and toolchain integration keep consuming engineering hours.
Efficiency problems span the journey from development to production. When development, training, and deployment run in different environments, teams repeatedly wrestle dependencies, configuration, and handoffs. A model validated in a research environment is not automatically ready for stable production service.
As more business lines onboard, problems once handled manually become unmaintainable. How models are deployed uniformly, how resources are allocated, who diagnoses failures — all require explicit platform capabilities and collaboration rules.
The goal of a cloud native AI R&D foundation, then, is to connect data, training, deployment, and operations — using standardized processes, automation, and resource scheduling to spare every project from rebuilding its own infrastructure.
Where CNCF and PyTorch Meet: Inside the Complete Workflow
Rather than reducing the foundation to any single project, the talk presented a layered collaboration model.
At the bottom, Kubernetes handles container orchestration, nodes, networking, and storage. One layer up, Volcano handles batch job scheduling, Kueue manages job queues and quotas, and HAMi provides heterogeneous device sharing and management. They all confront resource problems, but at different granularities: queues decide the rules by which jobs obtain resources; device management must also handle how a single card serves multiple jobs.
Above that sit training orchestration, model serving, and pipelines. Kubeflow Trainer, KServe, Argo Workflows, and their peers organize concrete tasks into manageable lifecycles. PyTorch and its surrounding training, fine-tuning, and inference tooling carry the model compute and execution.
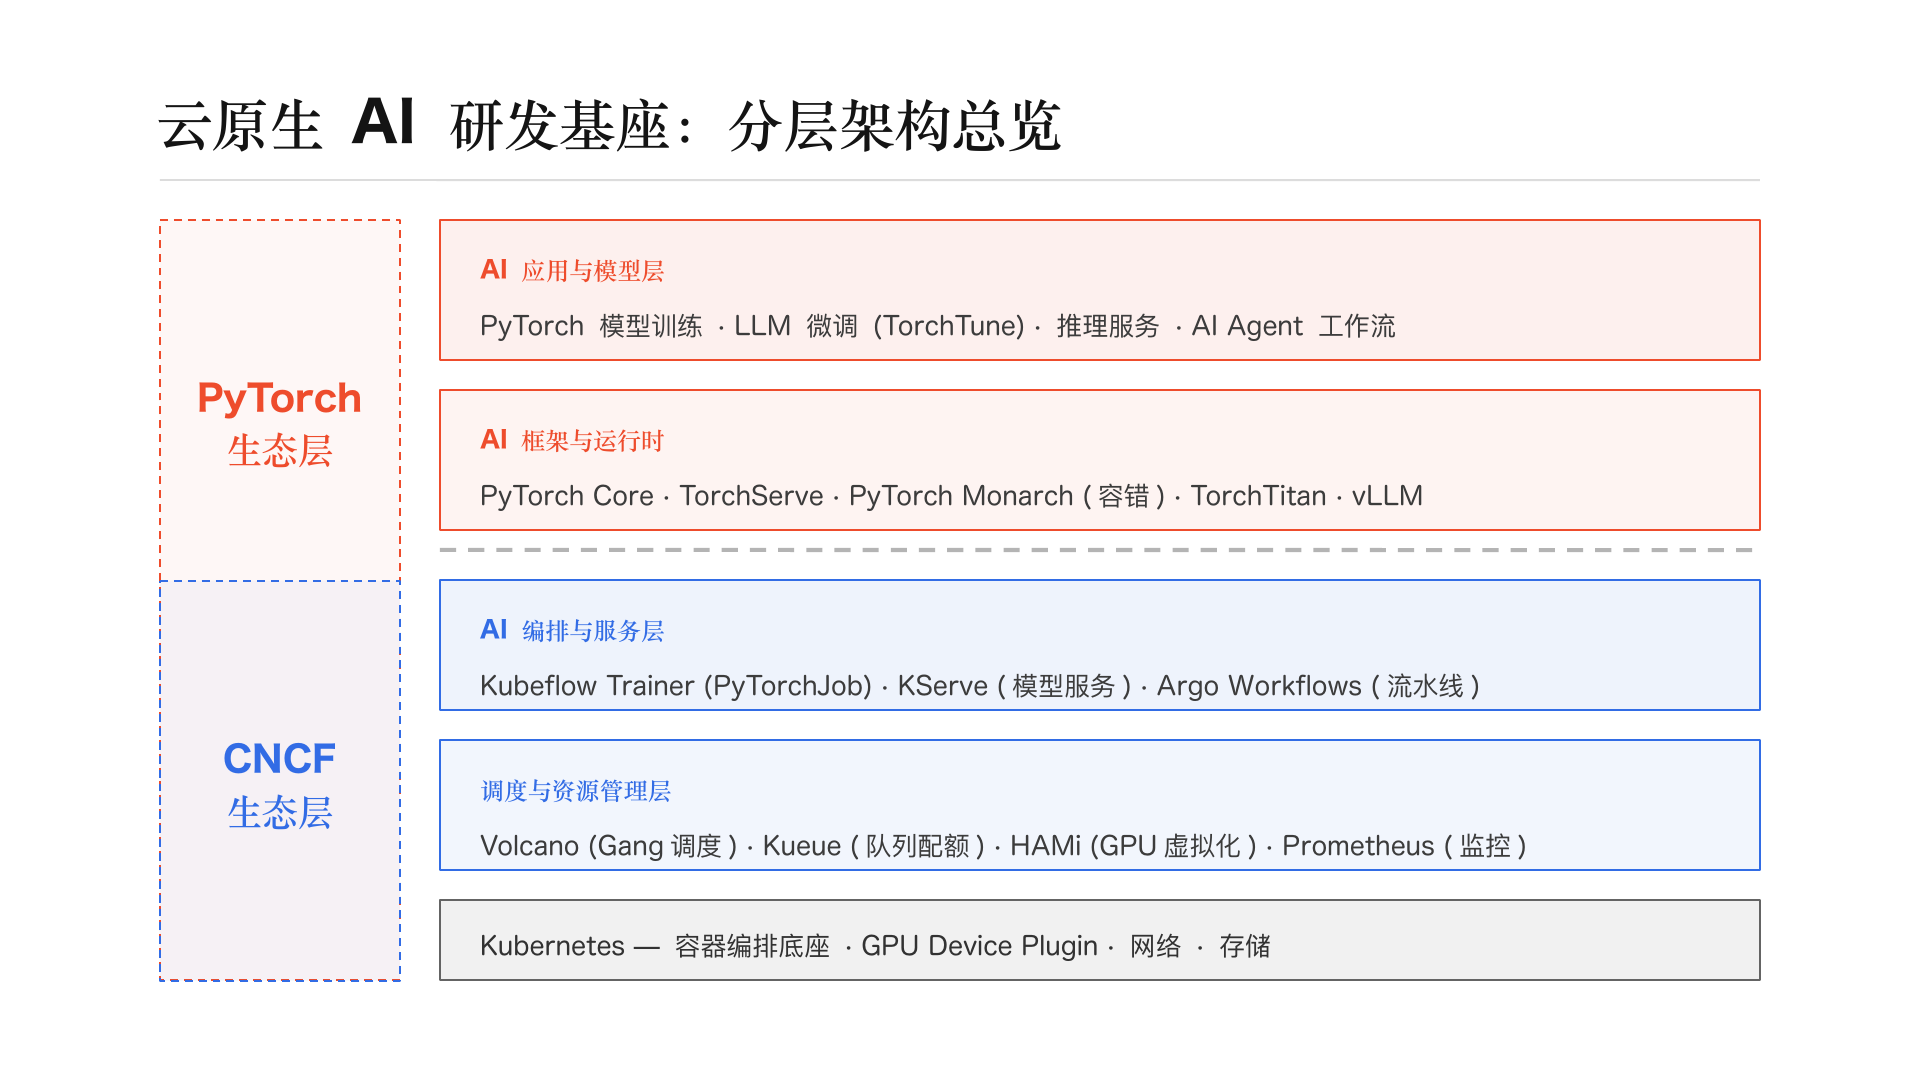
This division of labor helps platform teams answer a very practical question: when a bottleneck appears, which layer should change? Job queuing and slow model execution are not the same problem; queue configuration, device allocation, and the model runtime are not interchangeable.
The fact that components compose doesn't mean an enterprise must deploy them all at once. Decide first which training, inference, and resource governance capabilities the business needs, then pick the implementations — otherwise the platform grows ever more complex while the business still can't use it.
The Uber Case: Drawing the Lines Between Models, Execution, and Resources
Keith used Uber's Michelangelo platform to illustrate layered design for training and infrastructure.
In the architecture shown, PyTorch and DeepSpeed handle model training, Ray serves as the unified distributed execution layer, and Kubernetes orchestrates GPU cluster resources. Model definition, distributed execution, and resource management land on distinct layers, making their collaboration clearer.
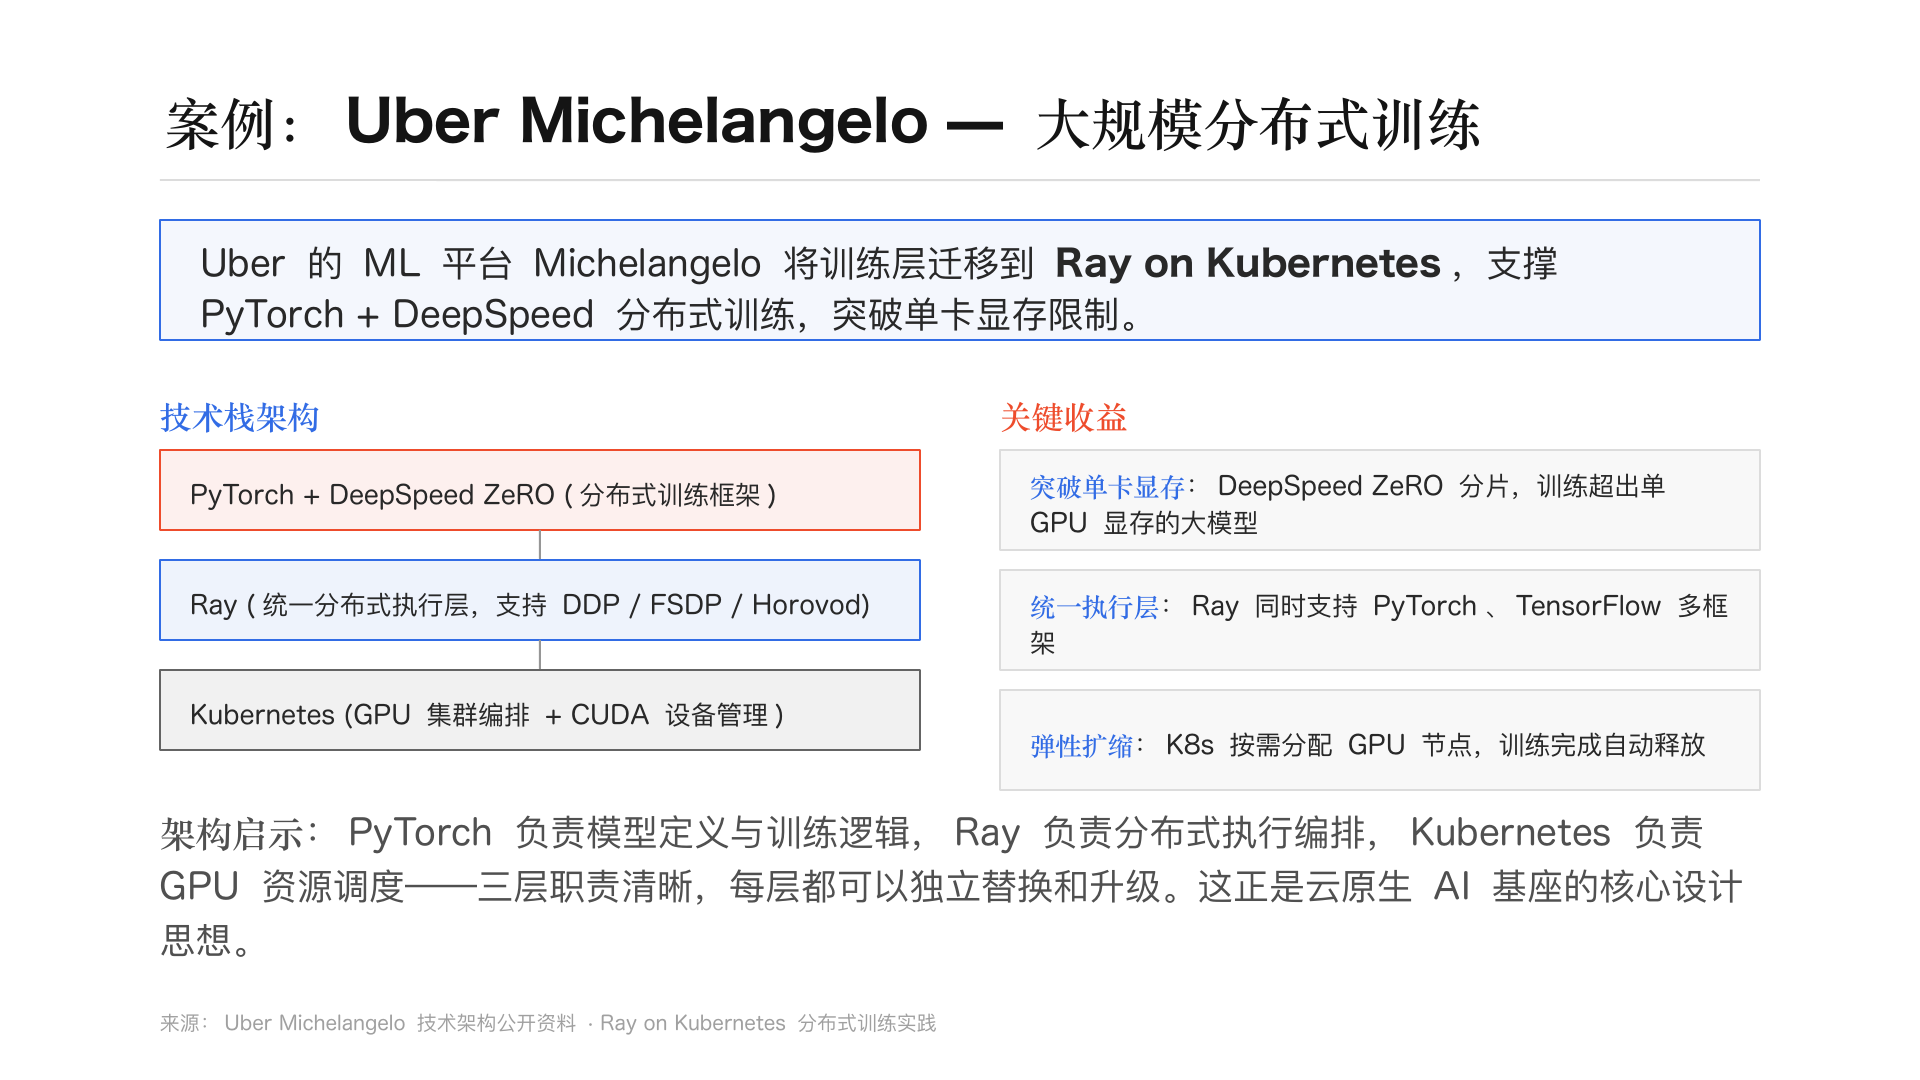
What's worth borrowing from this case is the responsibility boundaries — not the specific tech stack.
For a company that already has an AI platform, a framework upgrade should not force a rewrite of resource management; expanding GPU capacity should not make the algorithm team relearn every scheduling detail. Clean interfaces and layering leave room for future upgrades, replacements, and extension.
HAMi's Value: Heterogeneous Device Sharing and Resource Control
Back in the overall foundation Keith presented, HAMi addresses the resource management layer: letting tasks that suit sharing use GPUs on demand, and bringing different types of accelerators under unified management. Model training and execution still belong to the upper-layer frameworks; HAMi provides those workloads with device sharing, resource limits, and scheduling. The Uber case illustrates the layering method — the talk did not present it as a HAMi adoption story.
Keith also noted that HAMi-core has been adopted by KAI Scheduler — evidence that sharing controls can collaborate with different scheduling systems. For enterprises, adopting HAMi can start from the resource gaps of an existing platform; there is no need to treat model frameworks, workflows, and the scheduler as one monolith that must be replaced wholesale.
The combination still has clear boundaries. Different hardware, drivers, and adaptation paths provide different sharing and isolation capabilities, and user-space resource limits are not equivalent to hardware-level fault isolation. Platforms must verify with their own workloads that quotas take effect and that jobs don't interfere, then decide which workloads are fit for sharing.
Running One Complete Path Beats Stacking Components
In the latter half, Keith turned to compatibility. The same AI workload can produce different results under different GPU drivers, network configurations, or autoscaling behaviors. The environment underneath works, the model on top works — the combination still needs verification.
He introduced the Kubernetes AI Conformance effort, emphasizing standardized testing to reduce uncertainty between infrastructure and AI workloads. For enterprises, compatibility verification belongs inside selection and delivery, alongside testing under real business load — you cannot declare the system ready just from component names.
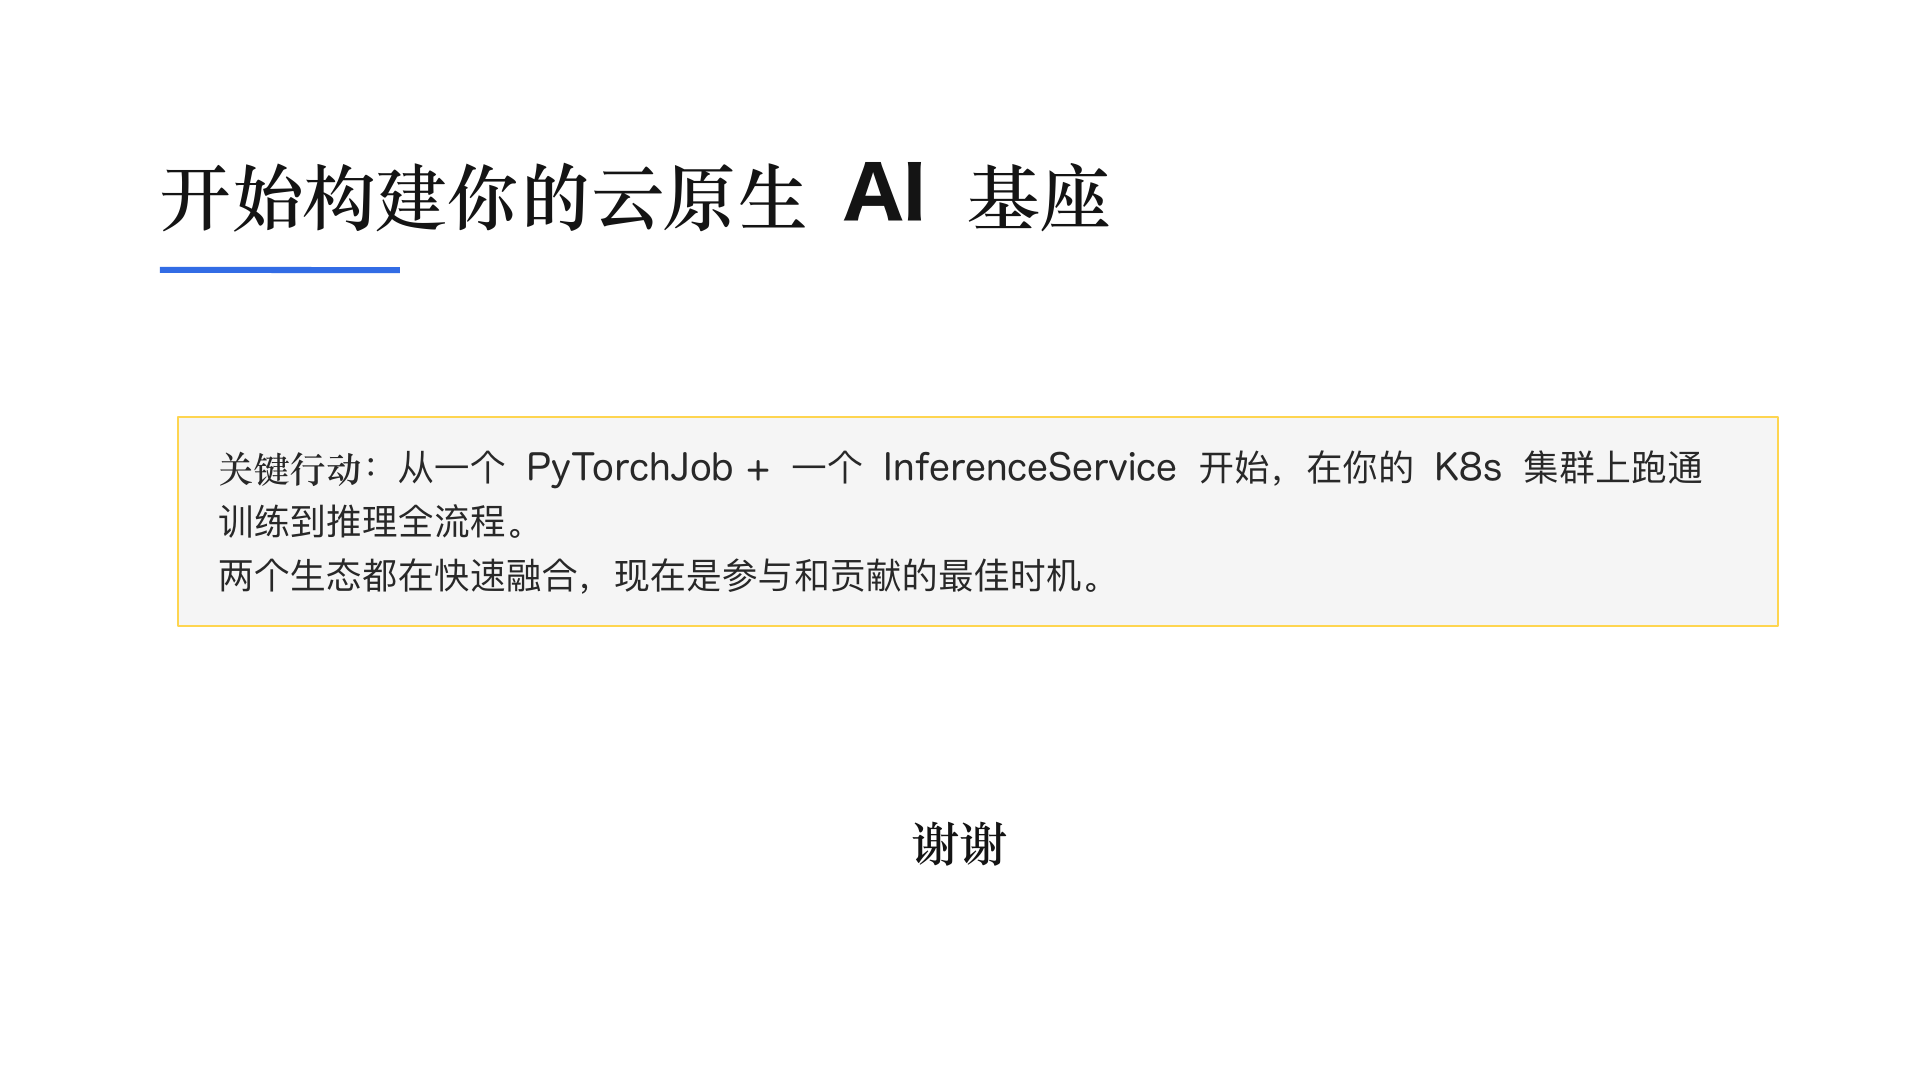
The starting point he offered is concrete: take one training job and one inference service, run the full train-to-infer path on your existing Kubernetes cluster, then progressively add resource management, monitoring, and automation.
For Dynamia, enterprise AI foundation building should be accepted against a real business chain: can training and inference run back to back, are resource requests honored, is post-sharing behavior observable? HAMi provides an open source foundation for heterogeneous compute management; adopting enterprises still own platform integration, device adaptation, and ongoing operations. Making those responsibilities explicit is what turns open source capability into infrastructure the business can actually use.
Video and Materials
- Bilibili replay: Opening Keynote | CNCF x PyTorch: Building a Cloud Native AI R&D Foundation for Industry Adoption — Keith Chan
- Event materials: HAMi Meetup Shanghai resource collection (GitHub)
Series
- Overview: HAMi Meetup Shanghai Recap
- (1) Where Does HAMi Fit in the CNCF × PyTorch Cloud Native AI Foundation? (this post)
- (2) After GPU Sharing: How HAMi 2.10 Improves Isolation, Scheduling, and Observability
- (3) Inference Control vs. GPU Resource Management: How llm-d and HAMi Can Work Together
- (4) Turning GPU Performance into Inference Service Capability: Lessons from Iluvatar
- (5) How iFLYTEK Manages Multi-Business GPU Sharing with Volcano + HAMi-core
- (6) How UCloud Turns HAMi Sharing into Ready-to-Use Development Environments
- (7) From User to Co-Builder: Why Enterprises Need a Sustainable HAMi Community