CETC Cloud Builds a Domestic GPU Sharing Foundation for a Portable Knowledge Base with HAMi
CETC Cloud needed to bring its intelligent knowledge base to project sites, running text generation, embedding, rerank, knowledge processing, and R&D debugging on a single set of portable devices equipped with domestic GPUs. The team introduced Kubernetes and HAMi to turn these limited GPUs — previously bound long-term to individual services — into resources that production models and Kubernetes dev environments can request, share, and schedule on demand.
On this resource foundation, text generation, embedding, and rerank models form a complete knowledge base pipeline; a single domestic GPU can also be shared by multiple Kubernetes dev Pods/containers through HAMi's virtualization.
Case Information
| Item | Detail |
|---|---|
| User | CETC Cloud technical team |
| Business scenario | An intelligent knowledge base appliance carried to project sites and run independently |
| Deployment environment | Kubernetes with on-premises domestic GPUs |
| Projects used | Kubernetes, HAMi |
| Core challenges | Multi-model coordination, shared production and development |
Scope of the Practice
| Knowledge base production pipeline | Kubernetes dev environment |
|---|---|
| Text generation, embedding, rerank | Multiple dev Pods/containers share a single domestic GPU |
The practice includes two GPU usage paths: knowledge base production models primarily use stable local resources, while Kubernetes dev Pods/containers share local domestic GPUs through HAMi.
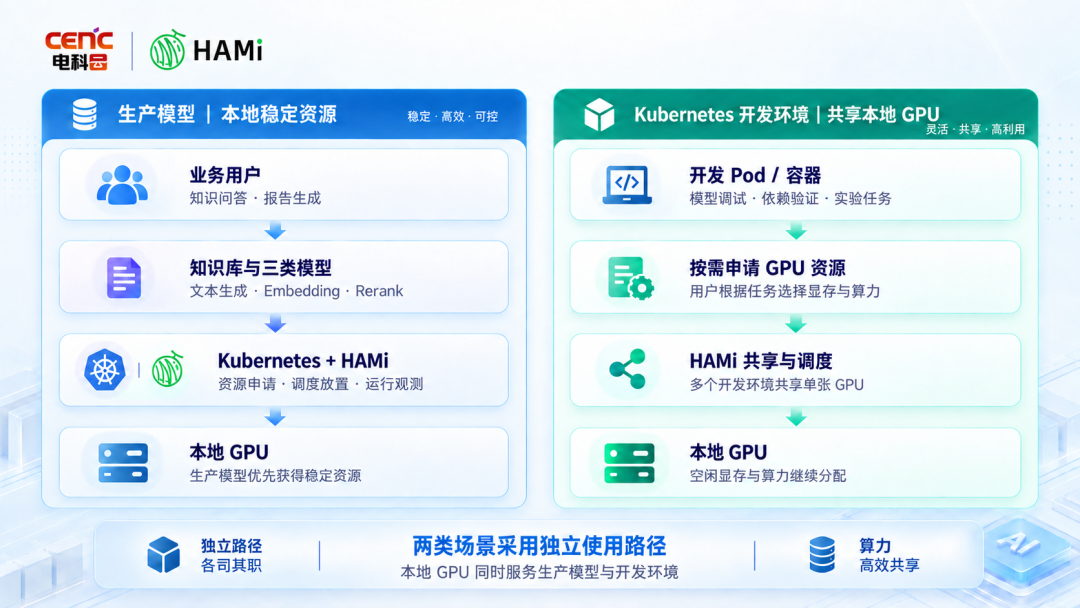
Figure 1: Production models and Kubernetes dev environments each use local domestic GPUs through HAMi.
One Portable Device Serving Both Production and R&D
The knowledge base's online Q&A depends on text generation, vector retrieval, and rerank; incoming documents go through parsing, chunking, vectorization, knowledge extraction, and index building. Engineers also debug models, validate dependencies, and run experiments inside Kubernetes dev Pods/containers. These workloads use GPUs in very different ways:
- Text generation models must stay online with a high VRAM baseline and are sensitive to response latency;
- Embedding creates periodic peaks during bulk document import and cares more about throughput;
- Rerank sits on the online retrieval path — short computations, but frequent;
- Knowledge processing and index rebuilds are batch tasks that must be isolated from online services;
- Dev Pods/containers are periodic and interactive, well suited to sharing GPUs within explicit resource boundaries.
If every service or dev environment keeps a whole card bound long-term, the limited devices are quickly exhausted logically; if the platform only chases the finest possible slicing, it amplifies VRAM shortage, queuing jitter, and fault propagation. The team needed each workload class to describe its own needs, with the platform placing resources based on device state and service levels.
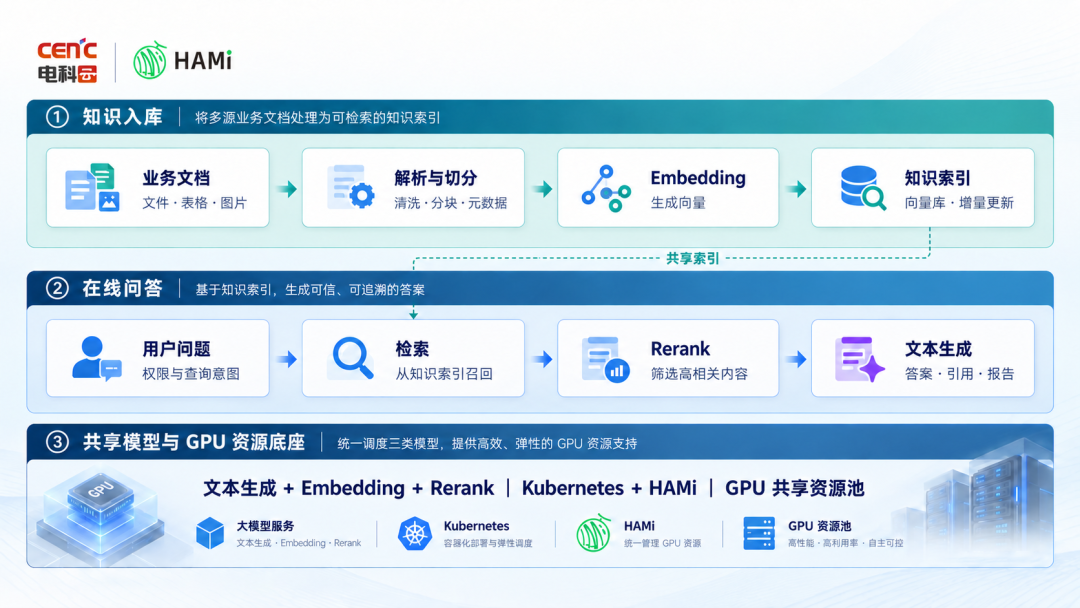
Figure 2: Business documents flow through parsing, embedding, and index building into the knowledge base; online questions return answers, citations, or reports via retrieval, rerank, and text generation.
Why HAMi
CETC Cloud wanted to keep the Kubernetes application delivery model while letting the platform understand whether domestic GPU devices can satisfy workload requests, and letting dev environments that suit sharing reuse the same physical GPU. HAMi's Kubernetes-native resource declarations, device-aware placement, device sharing, and runtime observability map directly onto these three needs.
HAMi's value is not just representing one physical card as multiple resource shares — more importantly, it establishes a common resource contract:
- Model services and dev Pods/containers declare the device resources they need, no longer relying on long-term manual card binding;
- Scheduling checks not just whether GPUs exist on a node, but selects based on available device state;
- Within what the actual device backend supports, multiple dev Pods/containers can share a single domestic GPU, each with its own resource boundary;
- Pods, containers, devices, and scheduling results can be correlated again, informing capacity observation and resource configuration corrections.
From Workload Profiling to Shared Domestic GPUs
The team built resource profiles from workload characteristics — model loading, peak usage, concurrency, latency, and long-run behavior — then translated validated needs into Kubernetes resource requests. Production models and dev environments follow different strategies:
- Stable boundaries for the online path. Text generation, online vector retrieval, and rerank get stable resources first.
- Periodic tasks queue and run off-peak. Document vectorization, knowledge extraction, and index rebuilds run when online load is low.
- Dev environments share a single domestic GPU. Multiple Kubernetes dev Pods/containers reuse domestic GPUs through HAMi's virtualization instead of each holding a dedicated device long-term.
- Configuration corrected by real load. Slicing granularity comes from baseline validation and runtime observation, not from a preset one-size-fits-all ratio.
This resource governance approach delivered four product capabilities:
- Text generation, embedding, and rerank are governed under one Kubernetes GPU resource workflow;
- Knowledge ingestion, retrieval, Q&A, and report generation form a complete running pipeline;
- Online services, batch tasks, and R&D debugging follow different resource rules;
- A single domestic GPU can serve multiple Kubernetes dev Pods/containers at once.
Quantified Results: Per-Device Dev Capacity from 2 to 30 Pods
On the same portable device with 8 domestic GPUs, the team compared resource capacity before and after adopting HAMi under identical conditions:
| Item | Without HAMi | With HAMi |
|---|---|---|
| Text generation models | 4 domestic GPUs, dedicated | Still 4 domestic GPUs, dedicated |
| Embedding and rerank | 1 dedicated domestic GPU each | 8 GB GPU memory quota each |
| Capacity left for dev environments | 2 GPUs remaining — only 2 dev Pods | Verified 30 concurrent dev Pods |
| Dev environment capacity | Baseline | 15× the original |
Dev Pods request their own memory quota based on task needs; the platform does not enforce a fixed uniform value. Under the current model quotas and dev load, the team validated 30 dev Pods running concurrently.
Single-Card Resource Comparison for the Embedding Model
The embedding model actually needs about 8 GB of memory on a 64 GB domestic GPU. Under whole-card dedication, the model uses only ~12.5% of the memory while the rest cannot be requested by other workloads; with HAMi, the team allocated 8 GB of memory and 20% of compute to the model and returned the remaining resources to scheduling. Using the same model image, request set, and concurrency configuration, the team compared whole-card dedication against HAMi slicing.
| Metric | Without HAMi | With HAMi |
|---|---|---|
| Embedding memory allocation | Dedicated whole 64 GB GPU | 8 GB on demand |
| Actual model memory need | ~8 GB | ~8 GB |
| Memory reusable by other tasks | 0 GB | 56 GB — 87.5% of the card |
| Embedding compute allocation | Whole card dedicated | 20% allocated, remaining 80% schedulable |
| Token throughput (tokens/s) | Baseline | Within 5% of dedicated mode |
| Model loading time | Baseline | Essentially unchanged |
| P95 request latency | Baseline | Essentially unchanged |
This same-card, same-model comparison shows that HAMi moved embedding from whole-card dedication to on-demand allocation, freeing memory and compute while keeping token throughput within 5%, with model loading time and P95 latency essentially stable — letting the same domestic GPU continue hosting dev environments or other sharing-friendly tasks.
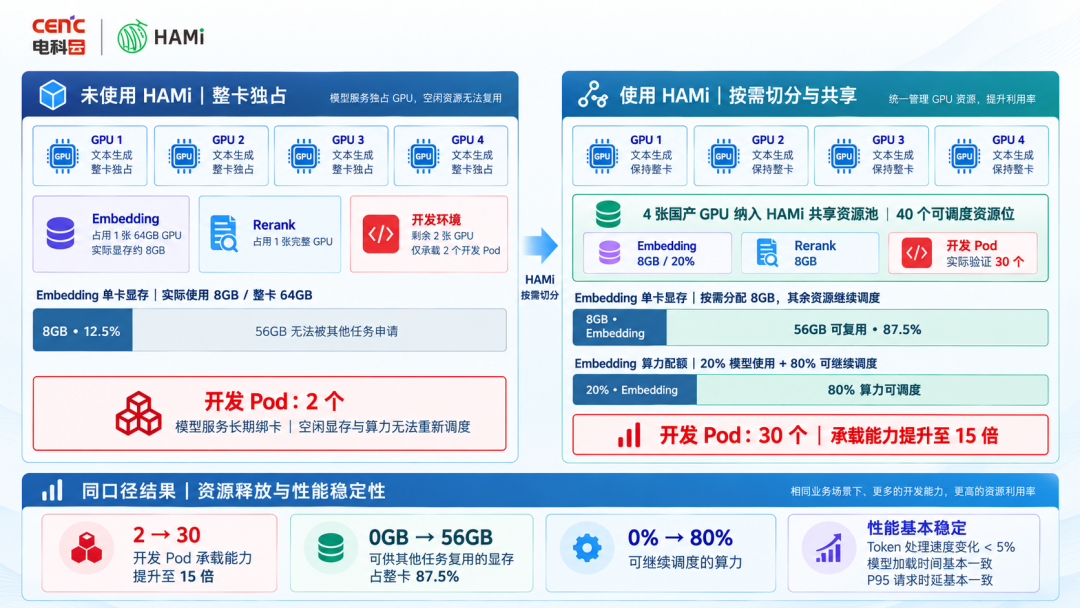
Figure 3: With HAMi, embedding moved from whole-card dedication to on-demand allocation, freeing 56 GB of memory and 80% of compute on a single card for other tasks; per-device dev Pod capacity rose from 2 to 30.
Lessons from This Practice
First, domestic GPU sharing should start from workload profiles, not from a unified slicing ratio. Production models, batch tasks, and dev environments differ in latency, memory, throughput, and isolation requirements — so should their resource policies.
Second, R&D environments are a major consumer of shared GPUs. Running dev environments in Kubernetes Pods/containers reuses the same resource declarations and scheduling as production services, while avoiding long-term device dedication per environment.
Next, CETC Cloud will continue improving capacity and health views for production and dev workloads, and adding reproducible experiment data across different models, networks, and calling patterns.
About the CETC Cloud Technical Team
The CETC Cloud technical team in this case owns product development and engineering delivery of the portable intelligent knowledge base, building capabilities around on-site local operation, knowledge processing, model serving, and dev environments.
Join the HAMi community to discuss shared GPU and portable AI practices.